Decision Models That Return No Text: Typed Answers for Governed AI
Much of the work that enterprises hand to large language models is a decision dressed up as conversation. Should this complaint go to the fraud team or customer service? Does this transaction need a second review? Teams prompt a general model, ask for a one-word answer and then write code to parse whatever comes back. Over three weeks in September and October 2026, a new class of AI decision models arrived that skips the pretence. They read the input and return a typed choice with probabilities, and they generate no text at all.
What arrived in September and October
TypeSafe AI, a company founded by a former OpenAI researcher, launched Jev on 15 September, describing it as a model for "smart if-statements": routing, classification, scoring and guardrails. It charges for input tokens only, with output free because there is no free-form output. On 29 September, OpenAI previewed a Decisions API powered by GPT-6 Luna. On 1 October, Cloudflare released Clef and Clef-flash as open-weight models under the Apache 2.0 licence, compatible with Jev's request format, and AWS open-sourced Strands Decider, a two-billion-parameter model. Several other labs released their own versions within days.
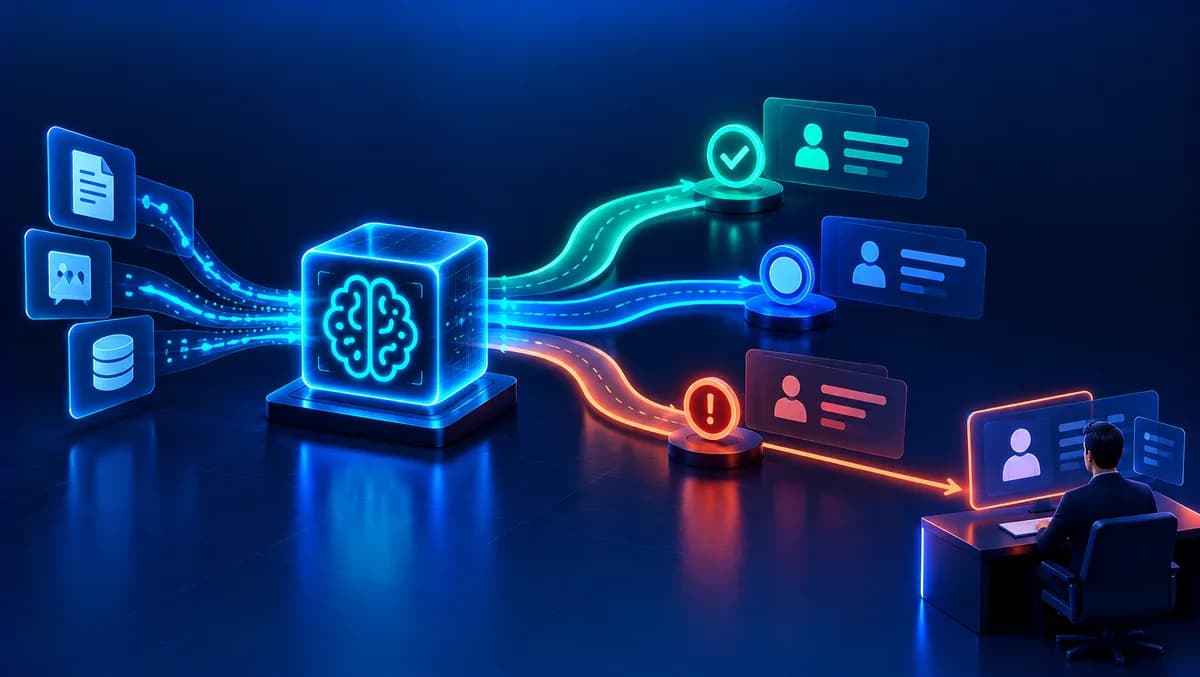
The mechanics are simple to describe. A request contains the input data and a set of typed questions. Clef, for example, can return a yes-or-no probability or a choice among up to 255 defined options. The model reads the input once and scores every allowed option. Because nothing is generated, it cannot answer with an option that was never offered.

Why typed answers suit governed automation
For teams responsible for controls, the appeal lies less in speed than in shape. A decision with a closed set of options can be tested exhaustively against a labelled sample. Every output is a structured record, so the audit log is a table of inputs, options and probabilities. There is no prose to interpret and no risk of a model inventing a category.
Probabilities also make thresholds explicit. A routing rule can send cases above 0.9 confidence straight through and send everything below it to a person, and that threshold can be documented, reviewed and adjusted by the risk team. With a chat model, the equivalent control usually depends on asking the model how sure it is, which is far less reliable.
Cost and latency matter at volume. Vendors report sub-second responses and prices that are a fraction of a general model's, though independent tests do not always match the claims. Cloudflare quotes a median latency of about 209 milliseconds for Clef, while one developer measured medians between roughly 520 and 730 milliseconds on launch week. The direction is clear even where the figures vary.
Where decision models fall short
A probability carries no reason with it. Many regulated decisions require an explanation the customer or the regulator can understand, such as the grounds for declining credit. A decision model can route an application to the right queue, and it should not be the component that tells a customer why they were refused. Those decisions still need reason codes, generated by a system designed to produce them, and a human accountable for the outcome.
Calibration has to be verified on the enterprise's own data. A model whose stated 0.9 means 90 percent correct on a vendor benchmark may mean something quite different on a bank's complaints or an insurer's claims. Reasoning-heavy judgements may also suit these models less well; early comparisons suggest the open models lead on classification and routing while Jev performs better on tasks that require more reasoning.
Where the selection almost broke
A team replaced the chat model behind its complaint-routing step with a decision model. On a labelled sample of past complaints, the new model was faster and more accurate, and its confidence scores looked well calibrated. It went live with a defined set of eight destination queues.
A month later, a new type of complaint began to arrive after a product change, one that belonged in none of the eight queues. A closed set of options has no way to say "none of these", so the model placed each new complaint in the nearest category, often with high confidence. The complaints reached a team that could not resolve them, and they bounced between queues for days before a supervisor noticed the pattern.
The team added an explicit "none of these" option to every routing question, and it now monitors the distribution of confidence scores each week, treating a shift as a signal that the categories need revisiting. Calibration is re-checked against a fresh labelled sample each quarter.
Decision models are a sensible addition to the enterprise toolkit, and they bring the predictability that governed automation needs. They are best suited to routing and guardrail checks, with explanations and final accountability handled elsewhere. A CTO considering them should ask whether the team has measured calibration on its own data and planned for inputs that fit none of the options. A deployment that has done both earns outcomes that survive scrutiny.
Related: Data Architecture
Tell us the number you need to move.
…outcomes that survive scrutiny.