When the Rubric Ages Faster Than the Model: Managing Evaluation Drift
An insurer's claims evaluation system scores every incoming claim against a rubric written last year, and its dashboards look healthy. Scores are stable, and the evaluator agrees closely with the reviewers sampled each month. In April, the policy wording for one product changed to add a new exclusion. Nobody updated the rubric. For the next quarter, the system kept scoring those claims against a standard the insurer no longer applied, and the stable dashboard was the problem. Evaluation drift happens when the rubric ages faster than the model, and it rarely announces itself.
Why rubrics age
Most discussion of drift concerns models: the data changes and the model's accuracy degrades. Rubric drift is different. The model may be performing exactly as designed, faithfully applying criteria that no longer describe what the organisation wants. Policies are reworded and regulations add requirements. Each change moves the true standard while the written rubric stays still.
The effect is subtle because consistency survives. An evaluator applying an outdated rubric produces results that agree with last month's results and often with reviewers who learned the same outdated standard. Consistency was the reason the organisation automated the evaluation, so it is natural to read stable scores as a sign of health.
Comparability across time suffers as well. When a rubric is edited informally, scores from before and after the edit look alike but measure different things. A trend line across that boundary tells a story that never happened.
Versioning the rubric like code
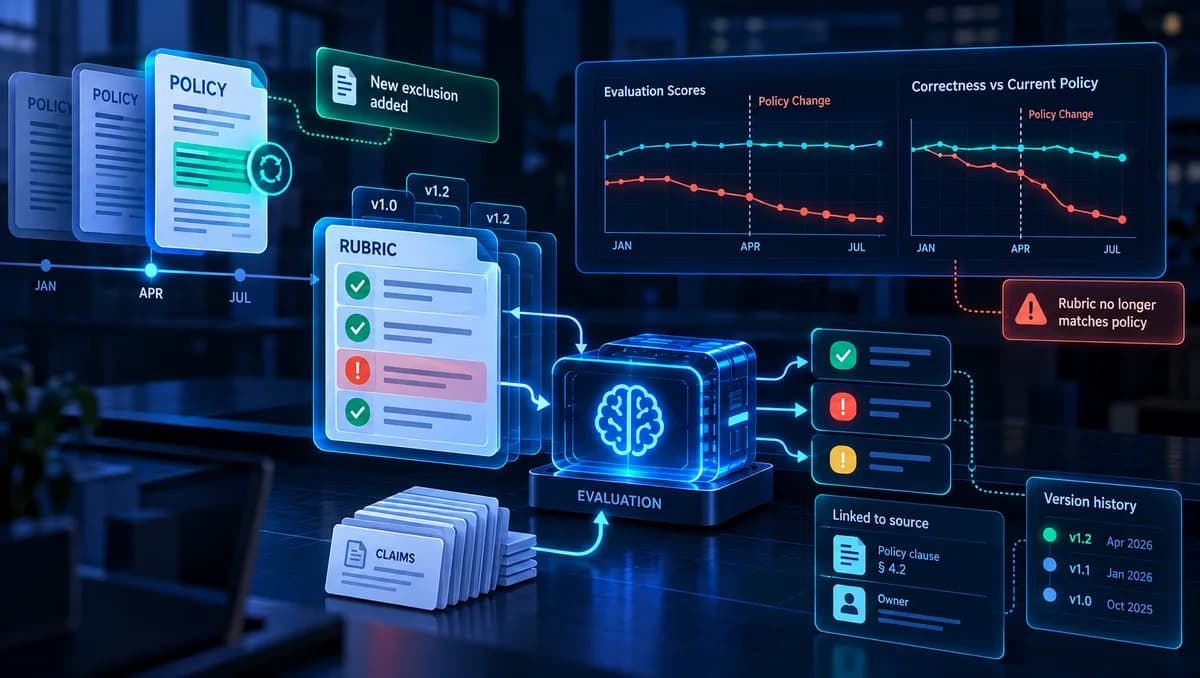
The remedy starts with treating the rubric as a controlled artefact. Every criterion carries a named owner and a reference to the policy clause or regulation it enforces. Changes are made through a reviewed process, and each produces a new version.
Linking criteria to sources makes change detectable. When a referenced policy document is revised, every criterion that cites it is flagged for review automatically. The owner decides whether the criterion changes, and the decision is recorded either way.
Every score carries the rubric version that produced it. When a new version takes effect, a reference set of past cases is scored under both versions, so the organisation can see what changed and explain any shift in its numbers. A rubric-based evaluation engine such as PRISM supports this discipline, recording the rubric version and the evidence behind every mark it gives.
Detecting drift before it matters
Not every change arrives through a document the system can watch. Some come from shifts in priorities or practice that nobody writes down promptly. Detection therefore needs signals from the evaluation itself.
The most useful is the human override rate, measured per criterion. When reviewers begin overruling the evaluator on one criterion more often, the criterion and the reviewers' standard have diverged, and someone needs to find out why. Shifts in the distribution of scores on a criterion are a second signal, particularly when the incoming cases have not obviously changed.
The calibration set itself needs regular refreshing. A set of reference cases scored once and kept for years will itself age. Adding recent cases each quarter, scored by experienced reviewers against the current standard, keeps the reference honest.
The exclusion the rubric never learned
The insurer at the start of this piece found the problem through its reviewers. Claims adjusters sampling the evaluator's work began overriding one criterion more often from May onwards. Each override was handled correctly case by case, and the overall agreement rate barely moved, because one criterion among many was a small share of the total.
In July, an analyst preparing a quarterly report noticed that overrides on that criterion had tripled since April. Tracing them back led to the new exclusion. The evaluator had been marking affected claims as eligible, and adjusters had been catching most of them. A sample review found a small number that had been paid before the adjuster's check, and those were recovered or written off with the product team's agreement.
The insurer linked every rubric criterion to the policy clauses it enforces and set an alert on override rates per criterion, so a rise is investigated within a fortnight. Rubric changes now go through the same review as policy changes, with the product owner signing both.
AI evaluation is only as current as the standard it applies. Keeping that standard current means versioning the rubric against its sources and listening when reviewers start to disagree with it. A head of operations should ask when each rubric criterion was last checked against the policy it enforces. An evaluation process that can answer, criterion by criterion, delivers outcomes that survive scrutiny.
Related: Agentic AI
Tell us the number you need to move.
…outcomes that survive scrutiny.