Preparing Pharma Field Teams: Compliant Detailing Practised With AI
A medical representative has four minutes with a cardiologist between outpatients. The doctor has read a competitor's trial and asks a pointed question about side effects. The representative, eager to keep the conversation going, says the product is completely safe. It is a natural reply and an unacceptable one, because India's Uniform Code for Pharmaceutical Marketing Practices bars the word "safe" without qualification. Pharma sales training with AI cannot make that four-minute conversation longer. It can make sure the representative has rehearsed it, against a demanding doctor, many times before it happens.
What the code asks of every conversation
The Department of Pharmaceuticals issued the Uniform Code for Pharmaceutical Marketing Practices, UCPMP 2024, in March 2024. Several of its clauses bear directly on what a representative says in a doctor's chamber. Promotion must be consistent with the terms of the drug's marketing approval. Claims of usefulness must rest on an up-to-date evaluation of the available evidence. The word "safe" may not be used without qualification, and "new" may not describe a drug that has been generally available in India for more than a year.
The code also places the responsibility on the company. Representatives must maintain a high standard of ethical conduct and must never pay, under any guise, for access to a doctor. Companies are responsible for their representatives' compliance, and the executive head of each company signs a self-declaration of compliance after every financial year.
That puts training at the centre of compliance. A company cannot supervise thousands of private conversations in clinics across the country. It can make sure every representative has practised the difficult moments, and it can keep evidence that they did.
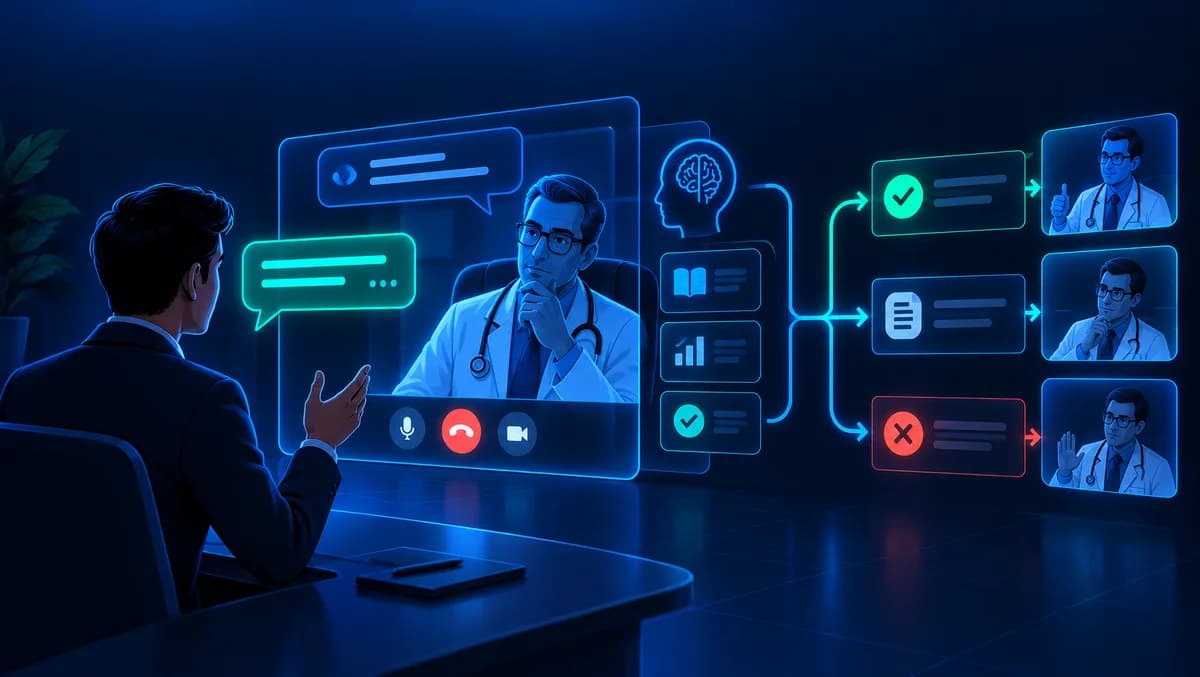
Rehearsal against an AI clinician
Classroom training teaches the approved claims. Role-play is where representatives learn to hold to them under pressure, and until recently good role-play needed a trainer playing a doctor, one representative at a time. An AI clinician changes that. It can play a sceptical senior consultant in Mumbai or a busy general physician in a district town, in Hindi or English, and it can raise the questions doctors actually ask.
The scenarios that matter most are the ones where representatives slip. A doctor asks about an indication the drug is not approved for. Another presses for a comparison with a competitor's product that the approved material does not support. Each scenario has an approved response, written and signed off by medical affairs and compliance, and the role-play tests whether the representative reaches it under pressure.
Scoring compares what the representative said with the approved claims library for the product. Unqualified safety claims and off-label statements are flagged with the exact words used, so the coaching that follows is specific. A short lesson on the gap arrives the same day. Rehearsal of this kind, with assessment that shows what stuck, is the work ATLAS is engineered for.
Keeping medical and compliance teams in charge
The AI clinician must never become a source of claims. Its role is limited to asking questions, so it never supplies wording a representative might repeat. The approved claims library belongs to medical affairs, and every scenario is reviewed by compliance before it reaches the field. When the product's prescribing information changes, the library and the scenarios change with it, and representatives receive the revised lesson within days.
Role-play results are coaching data, and they should be treated with care. Representatives practise better when a stumble in rehearsal is not held against them. Managers should see aggregated patterns, such as a region that struggles with competitor questions, while individual transcripts stay with the representative and the trainer. The company's compliance record needs evidence that training happened and covered the code, which aggregated completion and assessment data provide.
The best-scoring answer that should have failed
A pharmaceutical company introduced AI role-play for a new launch, and the scoring rewarded answers that were specific and grounded in evidence. In the first month, compliance reviewed a sample of the highest-scoring transcripts and found a problem. Asked by the simulated doctor about an unapproved indication, several representatives had answered fluently, citing published studies on that use.
The answers were accurate and backed by data, which is why the rubric scored them highly. They were also exactly what the code forbids, because promotion must stay within the terms of the marketing approval. Representatives were learning that a well-referenced off-label answer was a good answer.
The correction changed the rubric and the scenario together. Any discussion of an unapproved indication now fails the scenario, whatever its quality, and the approved response is a referral to the company's medical information service. Compliance reviews the rubric every quarter alongside medical affairs, and the top-scoring transcripts are sampled each month, because a rubric that rewards the wrong behaviour does its damage among the best performers first.
The four-minute conversation in the cardiologist's chamber is where a company's marketing code is kept or broken. AI role-play gives every representative the chance to rehearse it in their own language against a demanding doctor. A head of commercial excellence should ask whether the company could show which representatives have practised the off-label question and how they answered. A field force trained that way is one whose conduct holds up as outcomes that survive scrutiny.
Related: Healthcare & Life Sciences · Koita Foundation: An AI-powered knowledge hub with citation-backed retrieval across seven repositories
Tell us the number you need to move.
…outcomes that survive scrutiny.