Why Benchmark Scores Don’t Survive Contact With Production
A model selection often comes down to a table. Someone assembles the leaderboard figures, the candidates line up by score, and the highest number becomes the recommendation. It is a clean way to make a decision, it is defensible in a meeting, and it is one of the more reliable ways to choose a model that disappoints in production. The score was real. It just measured something other than the thing your deployment depends on, and the distance between those two things is where a confidently chosen model quietly underperforms.
The problem is that a public benchmark and a production workload are different environments, held well outside any framing of the benchmarks themselves as dishonest, and a number earned in one does not transfer to the other. A leader who understands why the transfer fails stops treating the leaderboard as a selection tool and starts treating it as what it is: a coarse filter that narrows a field, followed by the evaluation that actually decides, which is your own, on your own workload. The score gets you to a shortlist. It should never get you to a decision.
Why the number doesn’t transfer

Three mechanisms break the link between benchmark performance and production performance, and they operate whether or not anyone is acting in bad faith.
The first is contamination. Public benchmarks are, by definition, public, and public data has a way of ending up in training data. When a model has seen a benchmark’s problems, or problems very like them, during training, its score reflects partly its capability and partly its exposure. You cannot easily tell how much of a high score is genuine reasoning and how much is recognition, and the portion that is recognition will not appear when the model meets a problem it has never seen, which is every problem in your production traffic. The score is inflated by an amount you cannot measure, in a direction that always favours the benchmark over your workload.
The second is prompt sensitivity. A model’s performance is not a fixed property, it shifts with how the task is posed. Benchmark scores are produced with prompts tuned to elicit the model’s best performance on that specific test. Your production prompts are tuned for your task, your format, your constraints, and they will elicit different, usually lower, performance than the benchmark’s optimised phrasing. Two models that score identically on a benchmark can diverge sharply under your prompts, because the benchmark measured them at their tuned peak and your system operates them under your conditions.
The third is distribution. A benchmark measures performance on a defined set of problems. Production sends the full messy range of real inputs: the malformed, the ambiguous, the adversarial, the ones outside anything a test set anticipated. What matters operationally is consistency across that range and graceful degradation at its edges, and the benchmark, which measures the curated middle, tells you nothing about the edges where production failures actually happen.
The position I will hold
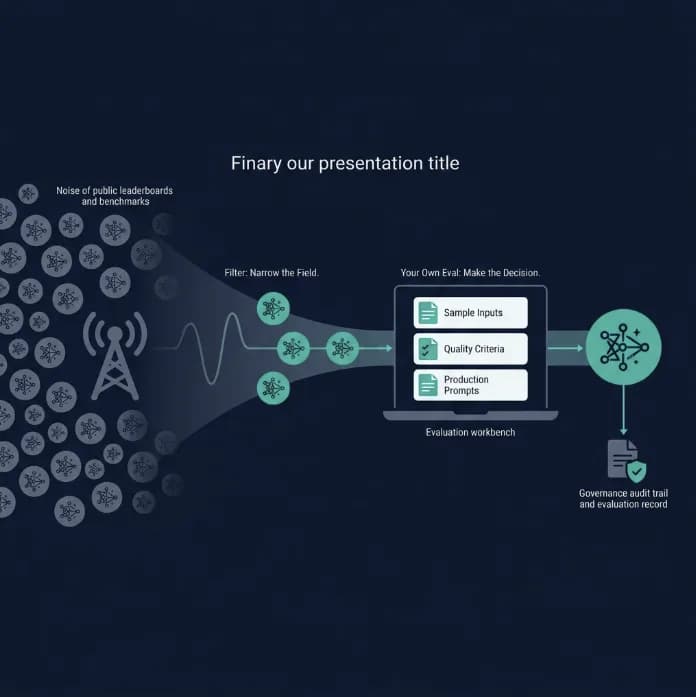
Here it is plainly. Your own evaluation set, built from your real workload, beats any public leaderboard for model selection, and an organisation that selects on public scores in place of building its own eval is choosing convenience over the one measurement that predicts production behaviour. The public benchmark is a filter, held well below the level of a selector, good for excluding models that are clearly not in contention and narrowing a large field to a testable shortlist. Using it as a selector is delegating your most consequential AI decision to a test that was not designed for your workload and was possibly seen by the models you are ranking.
Building your own eval is work, and the work is the point. It means assembling a representative sample of your real inputs, including the hard and the edge cases, defining what a good output actually is for your task, and measuring candidate models against that under your production prompts and conditions. This is an asset you maintain, held well outside a one-time exercise, extended as new failure modes surface, and repeat whenever you consider a model change. A production AI system selected against a real eval is selected on evidence that predicts its behaviour. One selected on a leaderboard is selected on a number that was accurate about a different environment.
What a real eval catches that a benchmark cannot
A workload-specific eval surfaces exactly the things the public score hides. It shows how consistently a model performs across your actual input distribution, held above the level of its peak. It shows how the model behaves under your prompts, held above the level of tuned ones. It shows degradation on your edge cases, where the operational risk concentrates. And because you built it, it is not contaminated: the model has not seen your proprietary inputs, so the performance you measure is the performance you will get.
The eval is also a governance asset, which is the part that compounds. A documented evaluation of candidate models against a representative workload, with defined quality criteria and recorded results, is exactly the evidence a regulator or an internal risk function wants to see behind a model choice. A governed AI deployment can show why this model was selected, on what evidence, measured how, and a leaderboard screenshot is held well below that standard. The eval you build to make a better selection is the same artifact that defends the selection afterward.
Where the leaderboard nearly decided
Consider a team that selected a model for a production workload on the strength of its leading benchmark position, over a close competitor that scored marginally lower. In production, the chosen model underperformed the expectation the score had set, and when the team finally built a proper eval on their own traffic, the marginally-lower-scoring competitor performed better on their actual inputs. The benchmark ranking and the production ranking were reversed, because the benchmark had measured tuned performance on possibly-seen problems and the eval measured real performance on unseen ones.
The score had answered a question the team had not meant to ask, held well outside any framing of it as a lie. The correction was to build the eval they should have built first, reselect on it, and keep it as the standing basis for every future model decision. The cost of building the eval was trivial against the cost of having deployed the wrong model on the strength of a number. That is end-to-end ownership of the selection decision, grounded in evidence from the environment the model will actually operate in.
The clean table that ranks the candidates by score is being convincingly precise about the wrong environment, held well outside any framing that would call it merely wrong. A benchmark is an honest measurement of a model on a public test, and a production deployment is not a public test, so the number that looked decisive was answering a smaller and different question than the one your selection actually poses.
The teams that choose models well treat the leaderboard as a filter and their own eval as the decision. They build a representative evaluation from real traffic, measure candidates under their own conditions, and keep the eval as a living asset that selects and defends every model choice they make. If you are about to select a model on the strength of a benchmark score, the question worth asking first is whether you have measured the candidates on your own workload, because that measurement, and not the leaderboard, is the only one that will still be accurate the day the model meets your production traffic.
Related: Data Architecture
Tell us the number you need to move.
…outcomes that survive scrutiny.